01 Infrastructure02 Tools03 Evalsfor AI agents

Agents that have to be right.

We build what AI agents run on when real money and real decisions are on the line: the servers they call, the tools they reason with, and the tests that prove they got it right.

Our tools work in
  • Claude
  • ChatGPT
  • Claude Code
  • Cursor
  • Hermes
  • OpenClaw
  • any MCP client

[ What we build ]

Three layers every serious agent needs.

01

Infrastructure

Servers agents can lean on.

Production tool servers on the edge, close to every user. Stateless, cached and rate-limited, read-only unless writing is the point. One link and they work in any agent.

  • Edge-hosted MCP servers
  • Abuse limits built in
  • No keys for the user to manage
02

Tools

Shaped for how models think.

Tools that tell the model exactly when to reach for them, answer in a shape it can reason over, and render a card a person can read at a glance. Fewer tools, each one finished.

  • Descriptions written for the model
  • Structured answers, not dumps
  • Cards for the human in the loop
03

Evals

Proof, not vibes.

Every tool ships with replayable test cases recorded from real data, plus live checks against the source. We find where an agent gets it wrong before your users do.

  • Recorded real-world fixtures
  • Live checks against the source
  • End-to-end runs in real AI apps

[ Flagship product ]

Lacuna Markets.
A Polymarket analyst inside any AI.

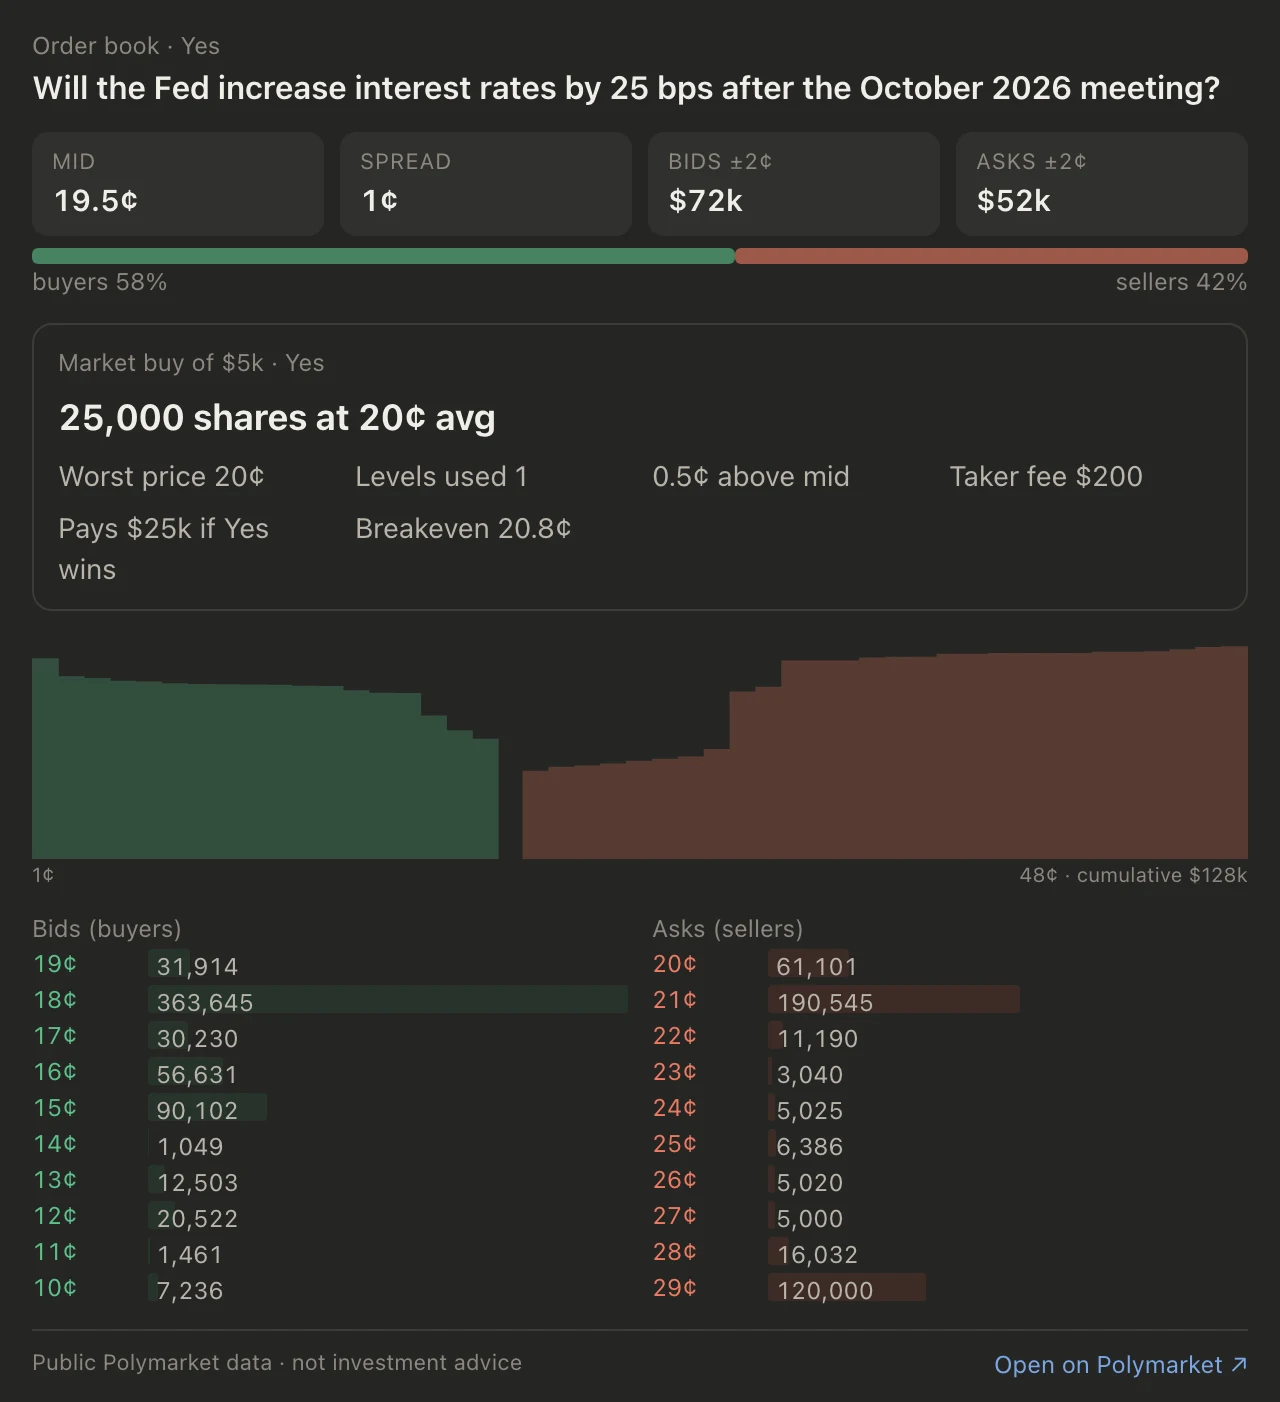
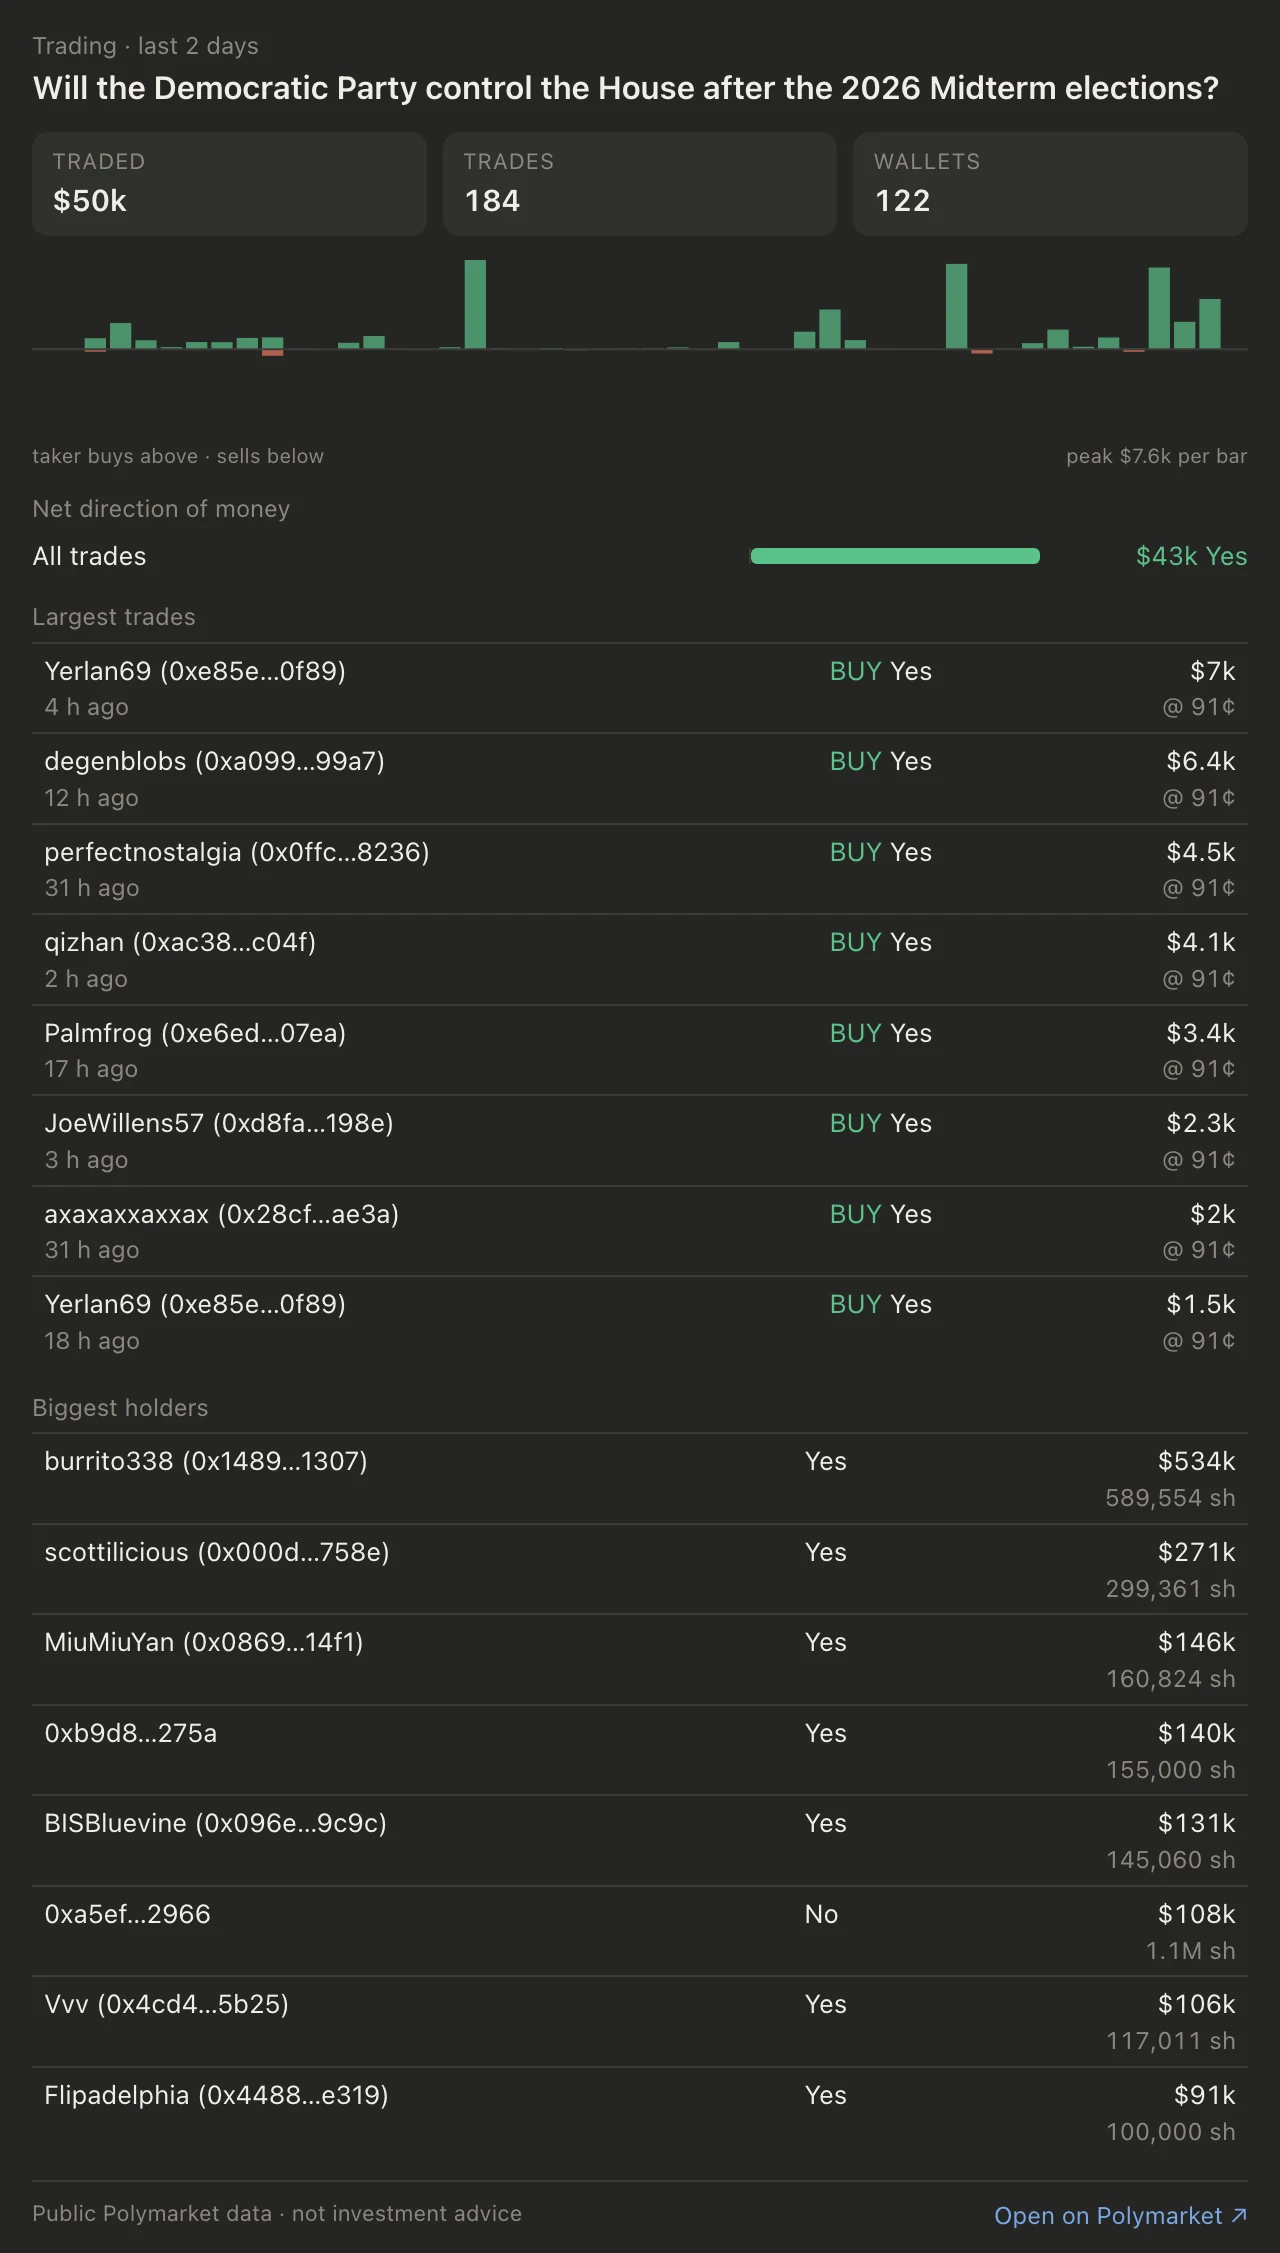
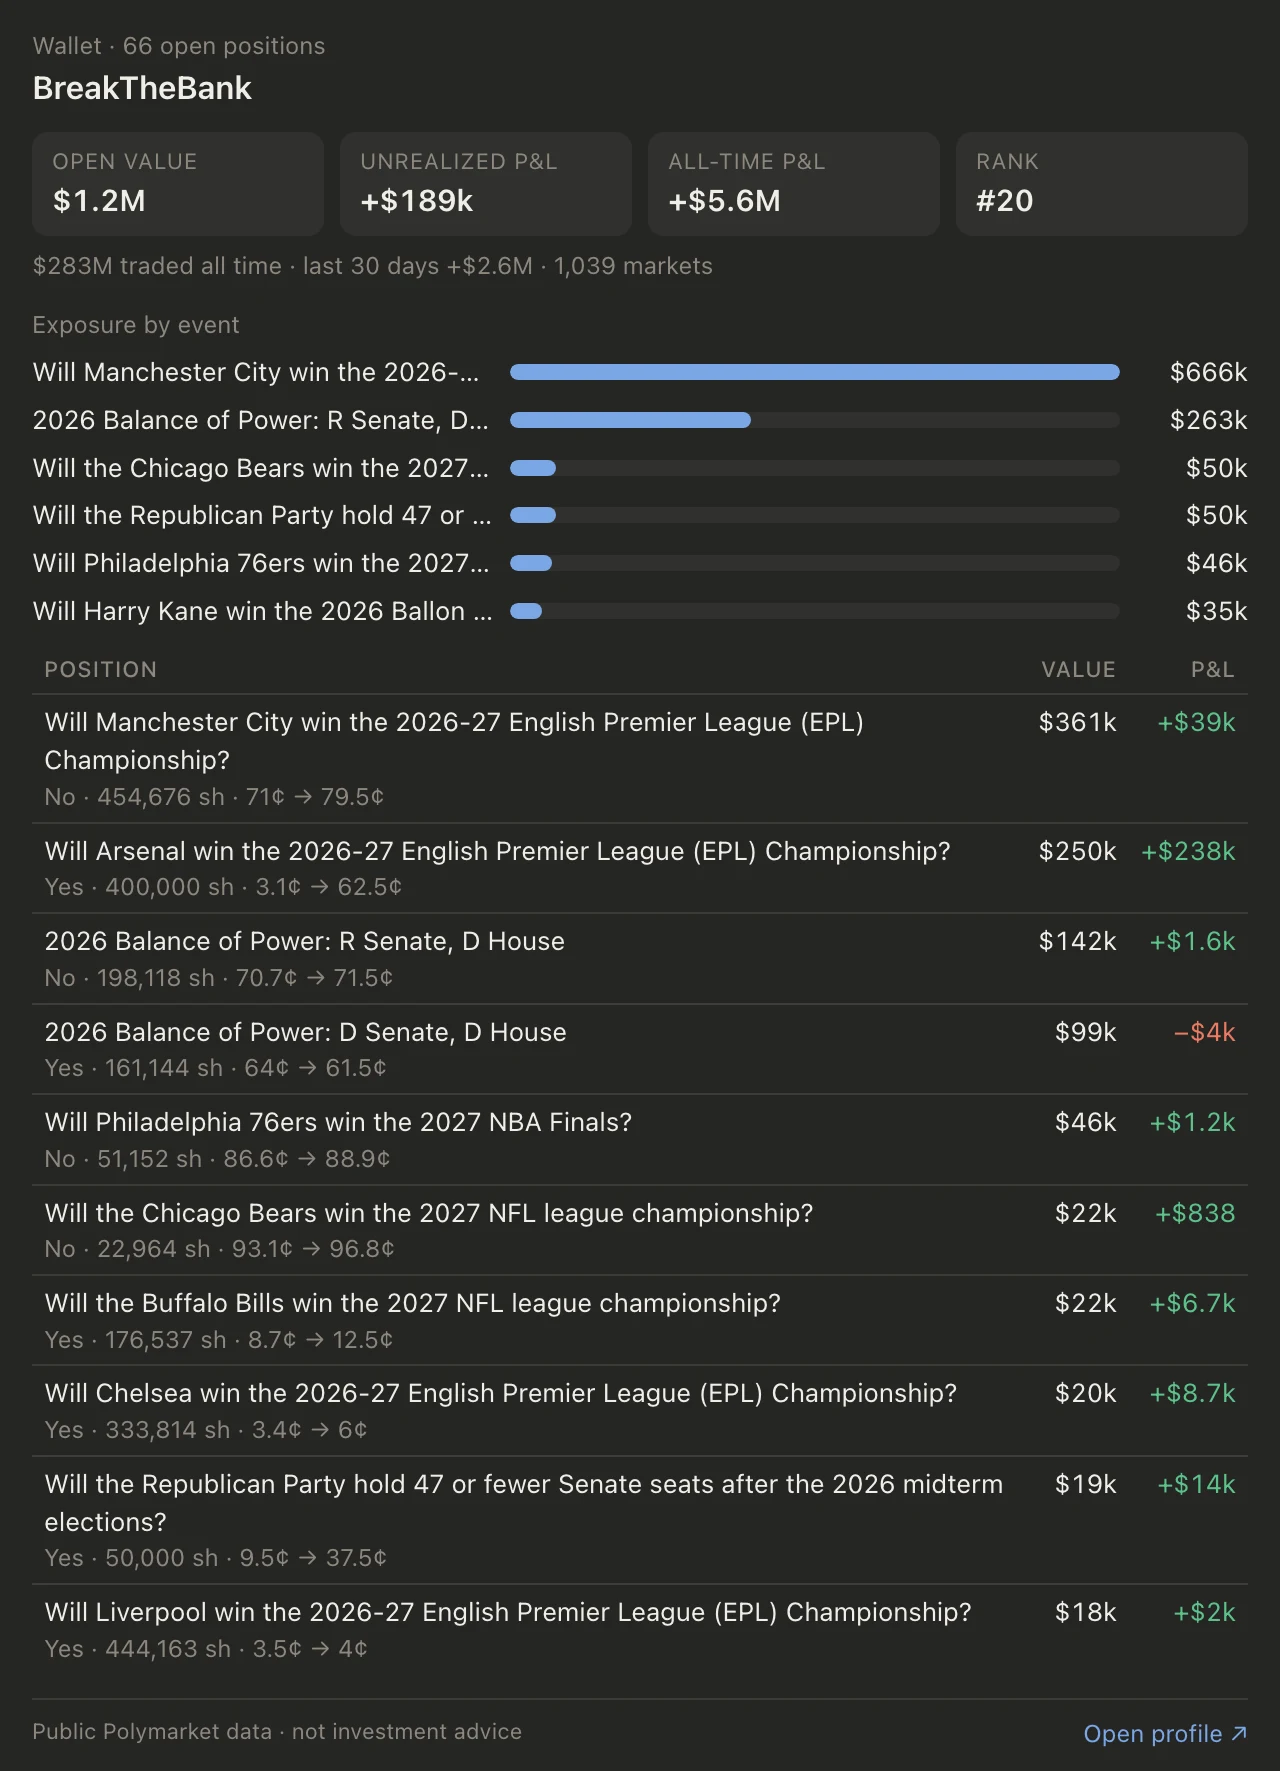
Ask about any market and get what decides it, what an order really costs against the live book, who's moving the price and whether that whale is any good. Free, read-only, and live in Claude, ChatGPT and any agent today.

Open lacuna.markets
Lacuna order book card: the real cost of a $5,000 buy on the Fed's October decision, with fee and breakeven.
What would $5k actually cost?
Lacuna flow card: net money per outcome, the biggest trades and top wallets on a market.
Who's moving this market?
Lacuna wallet card: a trader's lifetime profit, rank and open positions.
Is this whale any good?

[ Why prediction markets ]

The most honest test an agent can take.

Every forecast gets a price, a deadline and a final answer. An agent can't hide behind a nice paragraph: if it misjudged the odds, the market settles it in dollars.

That makes prediction markets our proving ground. We study how different model families reason, where they break, and how their failures differ, then turn what we learn into the tools and tests we ship.

The question we care about isn't whether a model can do a task once. It's whether you can predict how it behaves across conditions, over time, when nobody is watching.

[ How we build ]

How we build

  1. Read-only by default. An agent should never be one bad call away from moving your money.
  2. Real data in every test. Fixtures are recorded from live sources, not invented to pass.
  3. Works with any agent. Open protocols, one link, no lock-in to a single AI app.
  4. Numbers you can check. Every figure links back to where it came from.

[ Writing ]

Notes from running agents for real.

[ Work with us ]

Building an agent that has to be right?

hi@reasontech.org